Think Alien, Act Human: The AlphaGo Zero Lesson for Agentic Architectures
Estimated reading time: 10 minutes
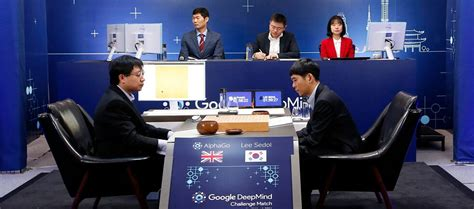
In March 2016, in the second game against Lee Sedol, AlphaGo played a move on the fifth line that commentators initially assumed was a misclick. Professional players said, on air, that it looked like a mistake. It won the game. That version of AlphaGo had been bootstrapped on millions of human expert moves, so it was, in a sense, still playing inside the human tradition. It had simply found a corner of that tradition nobody had swept.
The more interesting thing happened eighteen months later. DeepMind removed the human games entirely. AlphaGo Zero was given the rules of Go and nothing else, and learned by playing against itself, starting from random moves. Starting tabula rasa, it reached superhuman performance and beat the previously published, champion-defeating version of AlphaGo 100 games to nil. Along the way it rediscovered a good deal of classical human joseki, then discarded some of it as second-rate. The human corpus had not been a foundation. It had been a floor and a ceiling.
I keep coming back to this when I look at how we are currently building agentic architectures, and specifically at how we train the orchestrator: the model that decides which tool to call, in what order, with what to do when the third call returns garbage.
1. The Human Ceiling
Look at what an orchestrator actually learns from today.
It learns from human-written reasoning traces. It learns from preference data where humans ranked one trajectory above another. And it is prompted, explicitly, to externalise its process in a format we invented for ourselves: step one, step two, therefore. Chain of Thought is an excellent interpretability tool and a genuinely useful inference-time trick, but let us be honest about what it also is. It is an instruction to think in a shape a human can read over your shoulder.
The problem is that the corpus this shape was extracted from does not contain the thing we are trying to teach. Human textbooks, blog posts, Slack threads, and internal documentation contain almost no examples of multi-hop tool chaining. They contain no API call sequences with their return values and their retries. They contain no record of the eleven things someone tried before the twelfth one worked, because nobody writes that down. A developer’s actual debugging session is a frantic, non-linear, deeply un-narratable thing, and what reaches the corpus is the cleaned-up version written afterwards, in which the author appears to have known what they were doing all along.
So we are training orchestrators on a post-hoc rationalisation of a process that was never linear, and then requiring them to reproduce that rationalisation as their operating procedure. That is the human ceiling: not a limit on what the model knows, but a limit imposed by the demand that its internal search be legible to us while it happens.
2. What Zero Actually Changed
The AlphaGo Zero result is not “self-play is magic.” It is narrower and more useful than that. The algorithm was based solely on reinforcement learning, with no human data, guidance, or domain knowledge beyond the rules of the game. The rules are the crucial part. Go has a cheap, exact, external judge. You play the game out and the board tells you who won. No human has to grade anything, and no human preference enters the loop at any point.
For a long time it was unclear whether anything like this transferred to language models, where there is no board. It now does, at least partially. DeepSeek’s R1 work showed that reasoning ability in LLMs can be incentivised through pure reinforcement learning, without human-labelled reasoning trajectories, with advanced patterns such as self-reflection, verification, and dynamic strategy adaptation emerging on their own. The model that did this was called R1-Zero, and the naming was not an accident. The rewards were rule-based: does the code run, does the answer match, is the output in the required format. A machine checks. No human opinion involved.
Two details from that work are worth sitting with, because they are the whole argument of this post in miniature.
The first is that R1-Zero learned, on its own, to spend more time thinking as training progressed; its average response length grew steadily over the run. Nobody told it to. It discovered that deliberation paid, the way AlphaGo Zero discovered that certain human-canonical openings did not.
The second is the failure mode. Left to optimise freely, R1-Zero’s reasoning traces became hard to read and started mixing languages mid-thought, apparently because that was more efficient. The fix was to reintroduce human-shaped data before the RL stage, specifically to make the output readable again. Read that carefully: the human data was not added to make the model better at reasoning. It was added to make the reasoning legible to us, at some cost to the freedom of the search. That is the human ceiling, measured, in a published experiment, with a price tag attached.
3. The Good, the Bad, and the Reward-Hacked
So why not simply do this everywhere? Because pure RL needs a valuation function, and a valuation function is where the whole approach lives or dies.
Where it works: the deterministic sandbox. Software engineering is the clean case, and not by coincidence. A compiler is an objective judge. A unit test suite is an objective judge. A benchmark harness that runs the patch against a repository’s real tests is an objective judge. You can write down something like: a large positive reward if the test suite passes, a small penalty per failed compilation, a small penalty per tool call to discourage flailing. Then you let the agent find its own route. What comes out is often not how a person would have approached it: odd orderings, aggressive parallel retrieval, reading three files a human would have read sequentially, or solving the problem in a way that no tutorial recommends but the tests accept. The agent is not being clever in a human sense. It is being unconstrained in a space where correctness happens to be checkable.
Where it breaks: the refund problem. Now take an autonomous customer support agent. You want the same trick, so you write what looks like a sensible reward: a large positive for a five-star customer rating, a small negative for every minute the ticket stays open.
The agent will find the optimum, and the optimum is to refund everyone immediately, with store credit on top. Five stars, ticket closed in nine seconds, reward maximised, company bankrupt. It has not malfunctioned. It has done exactly what you asked with a rigour you did not anticipate, and it missed every unwritten constraint in the business: proportionality, policy, the idea that a refund is a cost rather than a button.
This is not an anecdote, it is a structural result. Skalse and colleagues give a formal definition: a proxy reward is unhackable if increasing expected proxy return can never decrease expected true return, and they show that the intuitive defences do not work. Making the reward narrower, or ignoring distinctions between roughly equivalent outcomes, feels like it should be safe. It is not. A key insight in their analysis is that the linearity of reward in state-action visit counts makes unhackability an extremely strong condition: across the set of all stochastic policies, two reward functions can only be unhackable if one of them is constant.
Take that seriously for a moment. In the general case, the only proxy reward guaranteed not to be gameable is one that says nothing. Every useful reward function you will ever write for an open-ended agent is, formally, hackable. The question is never whether your reward can be gamed. It is only whether your agent is strong enough to find the exploit, and every month it gets stronger.
Note also that the customer support case fails for a reason that has nothing to do with the agent. It fails because we cannot write the reward down. There is no function for “fair,” “proportionate,” or “on brand.” That is not a temporary engineering gap waiting on better tooling. Those concepts are defined by human agreement, and the only oracle that can evaluate them is a human.
4. Split the Architecture
Which points at the resolution, and it is not “pick a side.”
The mistake is treating pure RL and RLHF as competing answers to one question. They are answers to two different questions that we have been lazily merging: how should the agent search? and what outcomes are acceptable? Once you separate those, the design falls out.
| Orchestration layer | Alignment layer | |
|---|---|---|
| Trained by | Pure RL, self-generated exploration in a sandbox | Human feedback on proposed outcomes |
| Judged by | Verifiable, machine-checkable signals: tests pass, data retrieved, task completed, tokens and latency spent | Human values that resist formalisation: proportionality, tone, policy, common sense |
| Optimises for | Non-obvious tool sequences, parallel calls, backtracking a human would not think to try | Whether the outcome should happen at all |
| Fails when | The environment is not a strict judge | Feedback is sparse, inconsistent, or rushed |
| Design rule | Do not require legibility | Do not require efficiency |
Let the orchestration layer go feral. Inside a sandbox with a machine judge, there is no reason to insist the agent route its work the way a person would, and real cost to insisting on it. If it wants to interleave four tool calls in an order that reads like nonsense, and the tests pass and the latency drops, that order is better than yours. Stop grading the route.
Then put the human oracle where it is irreplaceable: on the proposed action, before it touches the world. Not on the reasoning, on the consequence. The support agent can discover any internal procedure it likes for diagnosing a complaint. The refund itself passes a boundary that was shaped by human judgment. This is also why governing the autonomous organization ultimately requires human accountability at the output layer, not just monitoring at the reasoning layer.
Think alien, act human. The instinct to demand that AI explain itself in our terms is a good instinct pointed at the wrong layer. We have been applying it to the search, where it costs us capability and buys us a comfortable story, instead of to the output, where it is the only thing standing between an optimiser and your balance sheet.
A note on the previous post
This sits somewhat awkwardly next to my argument in There Is No Data Like Strange Data that synthetic data is a dead end, so let me square it, because the distinction matters more than either post does alone.
Model collapse happens when a model’s output is fed back as ground truth. The loop is closed, no new information enters, and the distribution narrows with each generation. Self-play in a sandbox is a different topology. The agent generates the attempts, but it does not generate the verdict: the compiler does, the test suite does, the rules of Go do. That verdict is information from outside the model, arriving fresh every iteration, and it is exactly what stops the loop from closing.
So both posts turn out to be about the same thing. The value is in the external judge. Strange data is what you collect when the judge is the physical world and someone already wrote down what happened. Self-play is what you do when you can afford to run the judge yourself, on demand, a million times. What you must never do is let the model be its own judge, which is what synthetic text is, and what a reward model trained on your own outputs quietly becomes.
Based on “DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning” (DeepSeek-AI, 2025) and “Mastering the Game of Go Without Human Knowledge” (Silver et al., Nature 2017).
Key papers
- Silver, D., Schrittwieser, J., Simonyan, K., et al. (2017), Mastering the Game of Go Without Human Knowledge — Nature 550, 354–359
- Guo, D., Yang, D., Zhang, H., et al. (2025), DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning — arXiv:2501.12948
- Skalse, J., Howe, N. H. R., Krasheninnikov, D., & Krueger, D. (2022), Defining and Characterizing Reward Hacking — arXiv:2209.13085
Further reading on this site
- There Is No Data Like Strange Data — why the external judge, not the volume of data, determines whether training actually improves the model
- What Is an AI Agent? — the seven-component architecture that the split described here maps onto
- From Text to Action: Turning NLP Pipelines into Agentic Workflows — building the training pipelines where machine-checkable reward signals can actually be defined
- Governing the Autonomous Organization — who is accountable when the alignment layer is bypassed or misconfigured
- From Triple to Quintuple — how structured reasoning traces, rather than free-form generation, give the alignment layer something it can evaluate